
Technical Article
The Machine That Must Explain Itself
Why Trustworthy Physical AI Needs Evidence, Causal Provenance and Verifiable Explanations From Sensor to Action
Trustworthy robots must explain physical actions with synchronized evidence, causal provenance, uncertainty, safety context and verifiable outcome records for humans.
A humanoid earns trust when a human can reconstruct what it sensed, believed, decided, constrained, commanded and actually did.
Explanation Is Becoming a Physical-System Requirement
A machine that moves through the physical world leaves consequences behind it. It can lift the wrong object, apply too much force, enter a shared workspace, stop unexpectedly, recover from a disturbance, damage a component or protect a person. Once autonomy is embodied, the question “why did you do that?” is no longer a philosophical curiosity. It becomes an engineering question about traceability, safety, service, liability, trust and learning.
This is where robot explainability must separate itself from the fashionable idea that an AI system merely needs to produce a convincing natural-language answer. NIST’s four principles of explainable AI require an explanation, require it to be meaningful to the user, require it to accurately reflect the process that generated the output, and require the system to recognize its knowledge limits. [1] The NIST AI Risk Management Framework similarly treats explainability and interpretability as parts of a larger trustworthiness system that also includes validity, safety, security, resilience, accountability and transparency. [2]
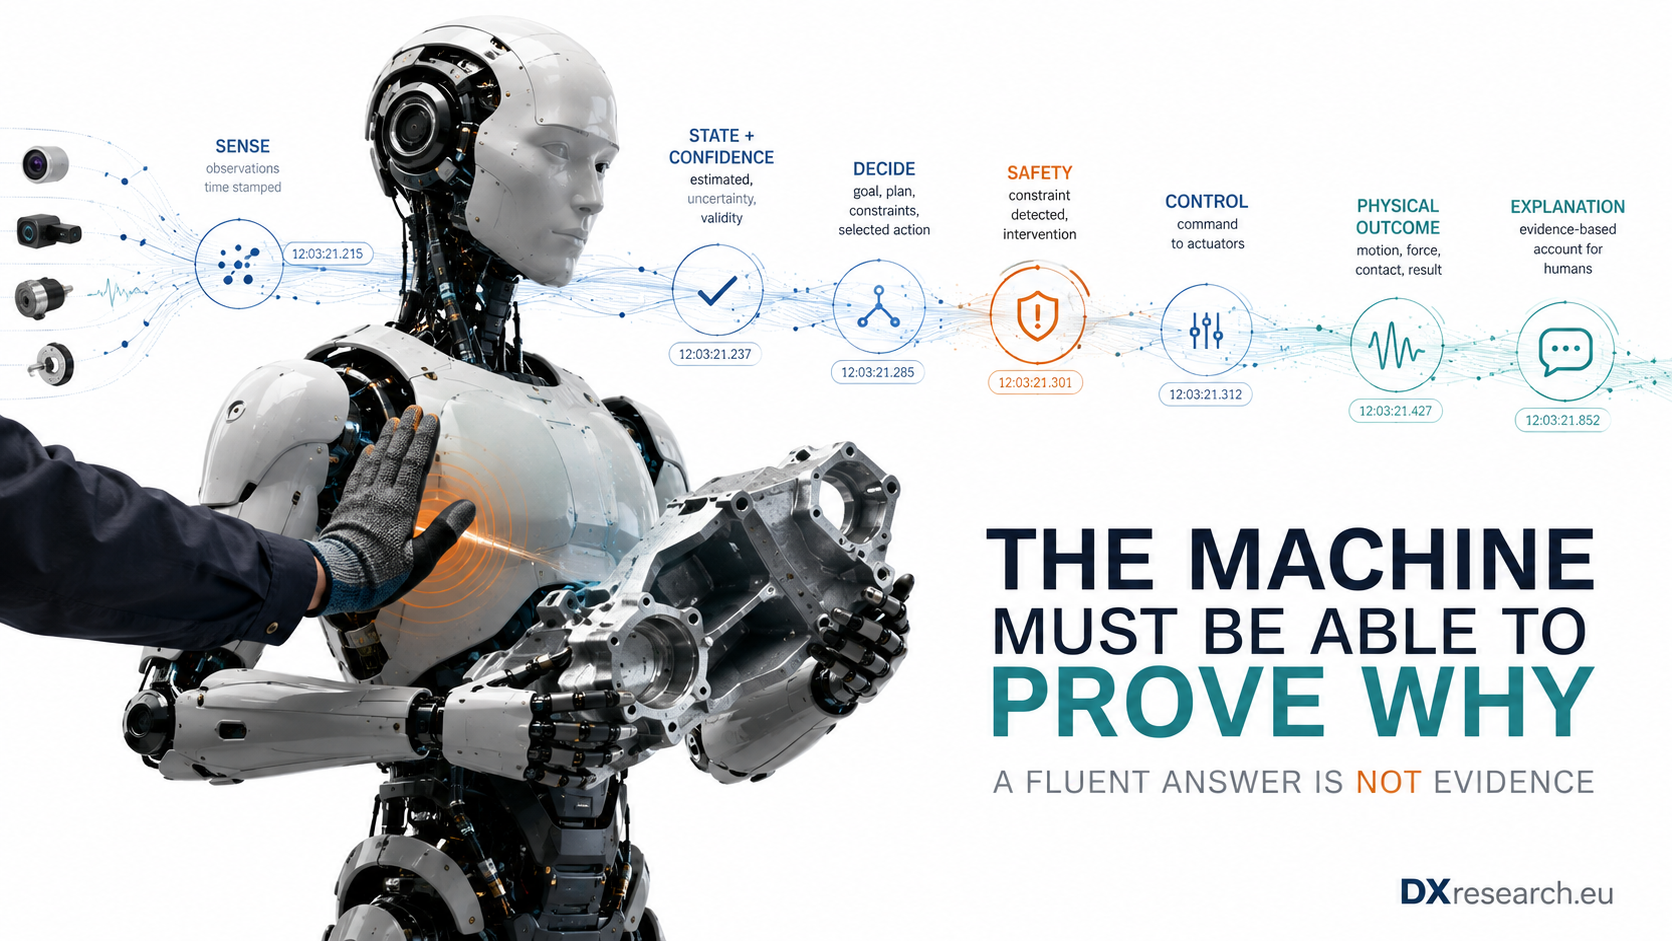
For Physical AI, the decisive word is accurately. The robot must not merely have a story. It needs an evidence chain.
The Explanation Must Follow the Action Chain
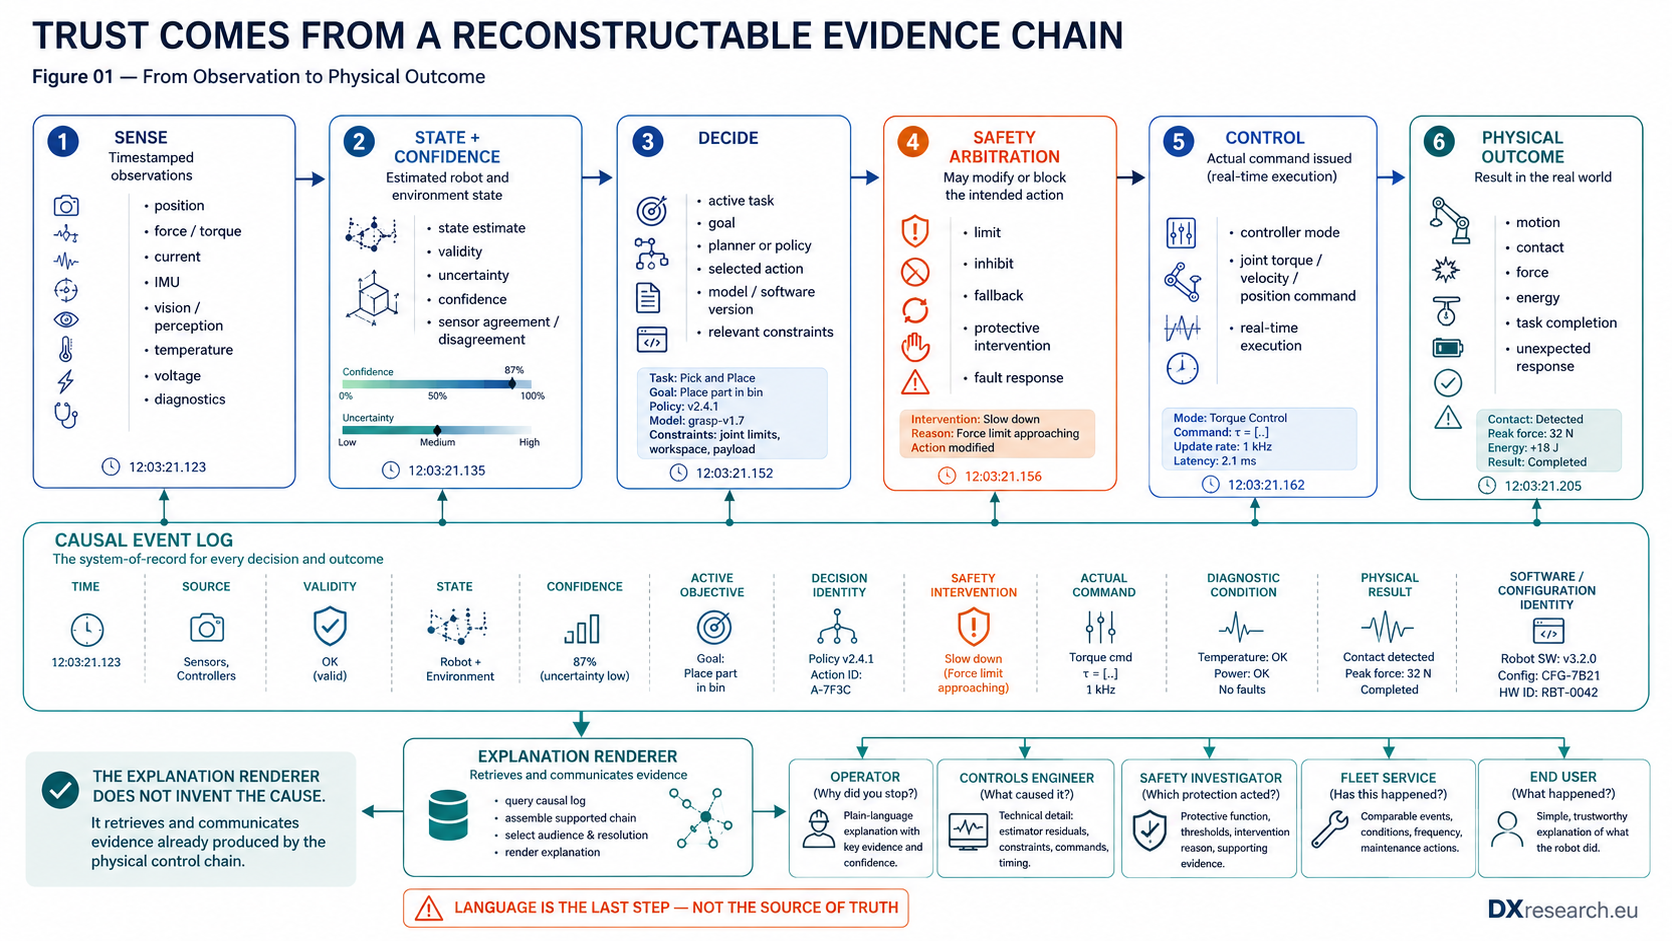
A useful robot explanation starts before the robot acts. It should be possible to reconstruct a sequence such as: what was observed; how valid those observations were; what state was estimated; how uncertain that state was; which task or objective was active; which action was selected; which alternatives or constraints mattered; whether a safety mechanism modified the request; which control command was actually issued; what the actuators did; and whether the observed physical result matched the intended result.
That sequence crosses conventional software boundaries. Perception may run on an AI accelerator. State estimation may be distributed. Whole-body planning may execute centrally. Joint control may run on local real-time microcontrollers. Safety functions may sit in separate hardware or software partitions. Current, position, force, thermal and voltage measurements may come from different nodes. A useful explanation therefore has to integrate evidence from the entire perception–decision–action chain rather than expose one neural network in isolation.
This system character is reflected in explainable autonomous robot research. A 2025 systematic review concludes that current techniques remain unable to fully cover the complex behavior of autonomous robots, whose actions emerge from multiple skills and diverse subsystems; the authors also identify a lack of conceptual consensus and robust evaluation methods. [5] Earlier survey work similarly argues that explanatory capability is a communication requirement for autonomous robots operating with humans, not simply a machine-learning visualization technique. [6]
The consequence is architectural: explanation cannot be bolted onto the user interface after the autonomy stack is complete. If the robot has not retained the relevant evidence, the interface has nothing trustworthy to explain.
A Causal Log Is More Valuable Than a Fluent Story
Recent work offers a useful direction. Galeas and colleagues store robot events as cause–effect pairs in a causal log. A human query retrieves the relevant causal event; a language model then refines the response for the user while the causal record remains the factual anchor. [7] That ordering is crucial.
For a production humanoid, the concept should be extended beyond high-level robot events. The causal event log should be able to bind together time, source, validity, state, confidence, active objective, decision identity, software or model configuration, relevant safety intervention, command, diagnostic condition and physical outcome. It does not need to store every raw sample forever. It does need enough structured evidence to reconstruct important decisions and transitions.
Consider a robot that suddenly stops while carrying a component. “I stopped because it was safer” is not an adequate engineering explanation. A stronger record might show that the wrist force estimate exceeded an expected envelope; the estimator confidence remained high because motor-current, joint-torque and wrist-sensor signals agreed; the planner’s nominal trajectory was therefore inhibited by a contact-protection rule; the safety/control layer commanded torque reduction and hold; measured joint motion decelerated within the expected envelope; and no protective stop channel reported a hardware fault. The natural-language explanation can be short. The evidence behind it cannot be fictional.
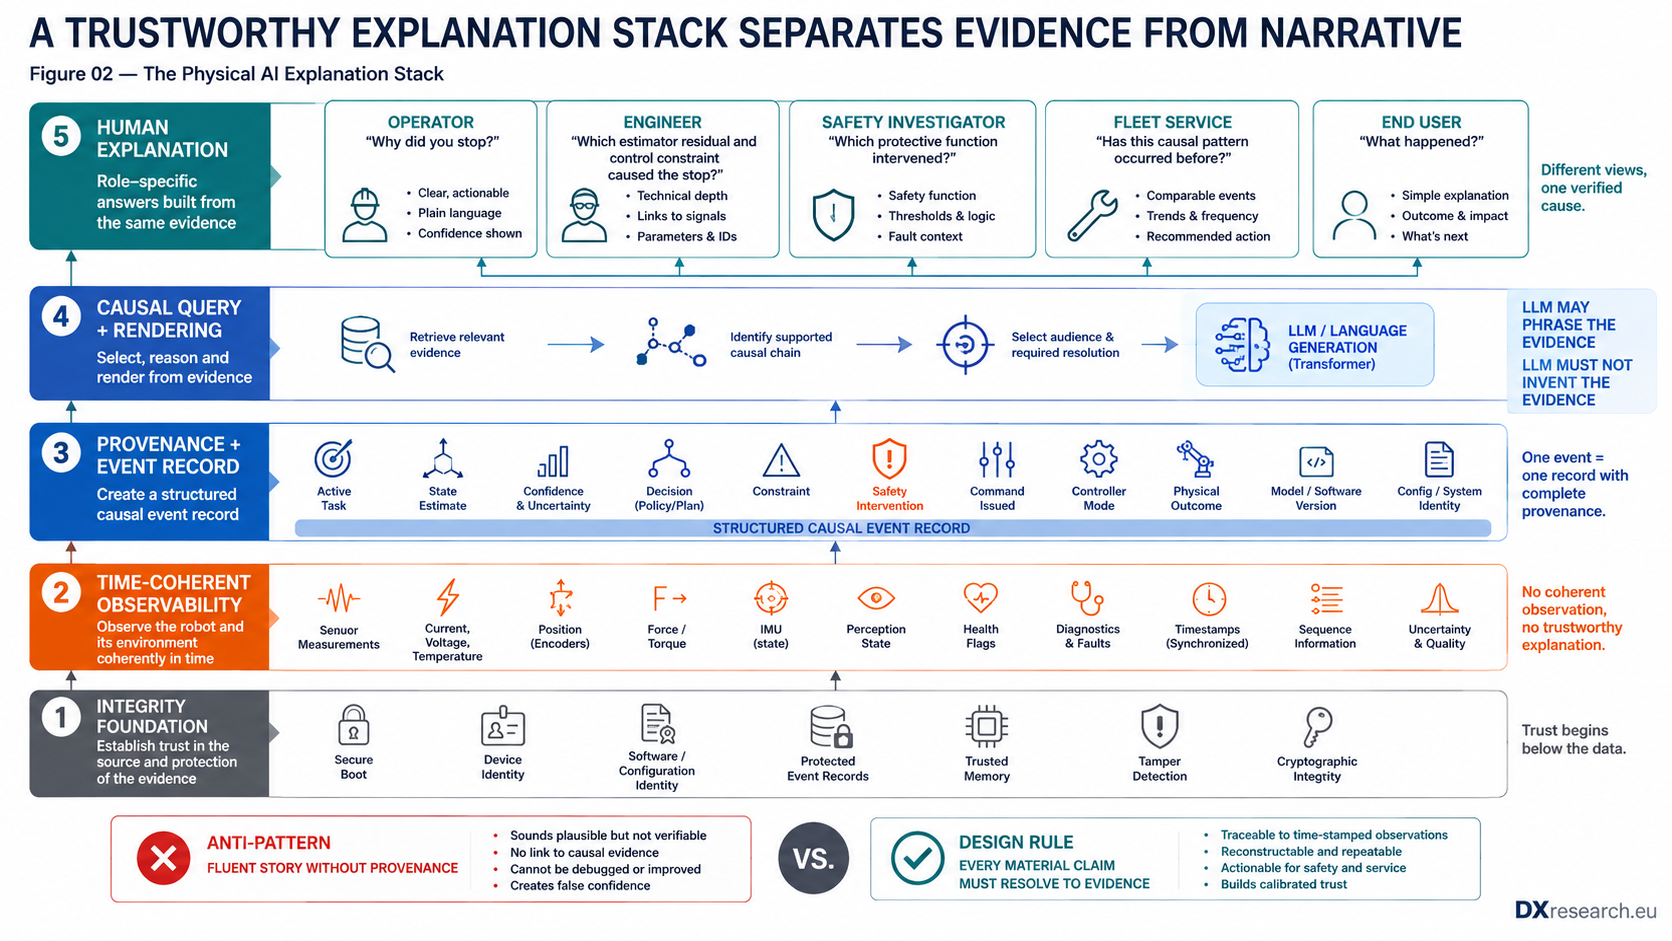
This distinction protects against one of the most dangerous failure modes of generative interfaces: narrative without provenance. A language model is very good at constructing a coherent explanation. That makes it useful as the last layer of the system, but dangerous as the first. Every material claim made by the explanation renderer should resolve to an observed or derived record with known source and validity. Where evidence is absent, the machine should say that the cause cannot be established from the retained record.
Trust Should Be Calibrated, Not Maximized
The objective is not to make humans believe the robot. It is to help them rely on it appropriately. A 2026 review of human–robot collaboration treats trust as a dynamic design target and emphasizes trust calibration: excessive trust can produce unsafe over-reliance, while insufficient trust causes needless intervention and lost productivity. It also identifies persistent gaps in standardized trust metrics, long-term validation and real-world integration of explainability with adaptive control. [8]
This changes the design of explanations. An operator may need a concise operational answer: “I slowed because the estimated payload shifted and the available contact margin fell.” A controls engineer may need the estimator residuals, time stamps, constraint activation and controller mode. A safety investigator may need independent fault channels, protective-function status and immutable configuration identifiers. A fleet-service engineer may need the same event compared with similar events across thousands of operating hours.
NIST explicitly recognizes that explanations must be meaningful to their audience. [1] A single universal explanation is therefore an anti-pattern. The underlying evidence should be common; the resolution and presentation should be role-specific.
Regulation Is Moving in the Same Direction: Traceability Before Storytelling
The European AI Act is not a blanket “robot explainability law,” and not every humanoid system will fall into the same risk classification. That distinction matters. But for AI systems that are classified as high-risk, the consolidated regulation requires technical capability for automatic event logging across the system lifetime and sufficient transparency for deployers to interpret system outputs and use them appropriately. It also connects transparency to human oversight and to mechanisms for collecting and interpreting logs. [3]
The current enforcement framework, updated in July 2026 after the amended timeline, states that rules for Annex III high-risk systems apply from 2 December 2027 and rules for high-risk AI systems embedded in regulated products apply from 2 August 2028. [4] These dates should not be misread as a reason to delay architecture work. Logging, traceability and interpretation are hard to retrofit once interfaces, compute partitioning and data ownership have been fixed.
For robot designers, the broader signal is clear: trustworthy autonomy increasingly requires evidence about how the system operated, not just a final output.
Safety Explanation Is Not the Same as Safety
An explainable robot is not automatically a safe robot, and an excellent diagnostic record cannot replace a safety function. Safety engineering requires deterministic risk reduction, defined safety functions, validation and appropriate independence. ISO 10218-1:2025 provides current safety requirements for industrial robots, while ISO 10218-2:2025 addresses integration into industrial robot applications and cells. Their scope is important: ISO 10218 explicitly excludes several categories such as public-access service robots, so it should not be presented as a universal humanoid standard. [9] [10]
Likewise, ISO 13849-1 and IEC 62061 provide machinery-safety frameworks for safety-related control systems. [11] [12] Explainability belongs beside these mechanisms as a way to reconstruct and communicate what occurred. It must not silently become part of a safety function unless it has been engineered and validated as such.
A good architecture therefore records the boundary between nominal autonomy and safety arbitration. If an AI planner requests motion and an independent safety mechanism limits or blocks it, the explanation should say so. The robot should never attribute a safety intervention to the planner simply because that makes the story sound coherent.
The Semiconductor Foundation of an Explainable Machine
The requirement to explain a physical action reaches all the way down to electronics. A humanoid cannot reconstruct a control decision if the current measurement has no reliable time relationship to the joint position, if the communication network loses event ordering, if a reset erases fault context, if configuration identity is unknown, or if a compromised software layer can rewrite the evidence after the event.
The first foundation is observability. Current sensors, position sensors, inertial sensors, force and torque sensing, temperature, voltage, power-stage diagnostics and communication status create the raw evidence. The quality of an explanation is bounded by the quality of the measurements that describe the physical state.
The second foundation is time coherence. The explanation must know which measurements belonged to which decision. Distributed clocks, synchronized sampling, sequence counters and bounded communication latency make causal reconstruction possible. “This current spike happened near the stop” is weaker evidence than “this current rise preceded constraint activation by 1.8 ms and the torque command changed in the following control cycle.”
The third foundation is local diagnostic context. Modern safety-capable microcontrollers can provide hardware fault monitoring, alarm handling and diagnostic registers. Infineon’s AURIX TC3xx Safety Management Unit, for example, includes alarm diagnosis mechanisms intended to support root-cause diagnosis and recovery strategies. [14] The point is not one MCU family; it is the architectural value of hardware-supported fault evidence that survives long enough to be associated with the event that matters.
The fourth foundation is evidence integrity. Secure boot and signed software establish what code was authorized to run. Hardware identity can establish which device produced a record. Protected memory, monotonic counters, hashes or signatures can make important logs resistant to undetected modification. The semiconductor architecture already spans motor control, sensing, power, connectivity, memory and hardware security in modern humanoid system proposals. [13] Explainability gives these functions another reason to be designed as a coherent system rather than as isolated components.
Design the Explanation Record, Not a Data Dump
There is a temptation to solve traceability by logging everything. A humanoid can generate enormous data volumes from cameras, tactile arrays, encoders, IMUs, motor-control loops and AI models. Indiscriminate recording creates bandwidth, storage, privacy, cybersecurity and fleet-cost problems without guaranteeing that an engineer can reconstruct an event.
A better design uses layered retention. High-rate local ring buffers retain the seconds around an anomaly. Structured event records retain transitions, causes, controller modes and diagnostic context for longer periods. Fleet systems retain aggregated evidence and recurring signatures. Critical safety or service events trigger promotion of selected data from volatile buffers into protected nonvolatile storage.
The record should also distinguish observed facts from estimates and inferences. “Joint position = 34.2°” may be a measured value. “Payload shifted” is an inferred state. “Human entered workspace” may be a perception classification with confidence and provenance. “Protective stop active” may be a safety-channel fact. Mixing those categories makes explanations look more certain than the machine actually was.
This is where causal provenance and explanation accuracy become practical engineering concepts. The system should know not only the value it used, but where that value came from, which version generated it, how confident the system was, and whether later evidence contradicted it.
A Practical Explanation Contract for a Humanoid
A scalable platform can define an “explanation contract” across subsystems. Every safety-relevant or operationally significant action should be reconstructable through a small set of common fields:
| Question | Required evidence | Typical source |
|---|---|---|
| What did you observe? | timestamped input, source, validity | sensors, perception nodes |
| What did you believe? | state estimate, uncertainty, confidence | estimators, world model |
| What were you trying to do? | task, goal, plan identifier | task/planning layer |
| Why this action? | selected action and relevant constraints | planner/policy/arbitrator |
| Did safety change it? | limit, inhibit, fallback, fault state | safety layer |
| What command was sent? | actual control command and mode | real-time controller |
| What happened physically? | motion, force, contact, energy, completion | actuator and body-state feedback |
| Can I trust the record? | device, software/configuration identity, integrity status | secure hardware and lifecycle system |
This contract creates interoperability between AI, control, safety, service and fleet engineering. It also makes testing possible. A validation team can deliberately introduce perception ambiguity, communication delay, actuator saturation, sensor disagreement or a safety intervention and verify that the resulting explanation is faithful to the actual control chain.
Measure Explanation Quality Like an Engineering Function
The chapter’s strongest technical consequence is that explainability needs KPIs. “Users liked the explanation” is useful, but insufficient. A Physical AI system should be tested for at least five properties.
Coverage: what proportion of defined significant events can be reconstructed? Faithfulness: does each explanatory claim resolve to the real decision and control evidence? Latency: how quickly can a useful explanation be produced after an event? Resolution: can the same evidence support operator, engineering and investigation views? Integrity: can the system detect missing, corrupted or configuration-mismatched evidence?
A sixth metric is equally important: calibration. Does the explanation make uncertainty visible rather than suppress it? If perception confidence was low, the explanation should say so. If the record cannot distinguish between two plausible causes, it should not manufacture certainty. This is the machine equivalent of intellectual honesty.
The Machine Should Be Able to Say “I Don’t Know”
The most trustworthy explanation may sometimes be incomplete. A robot can lose sensor data, reset, operate outside a model’s validated domain or encounter an unmodeled physical interaction. The system should make those knowledge limits visible rather than backfill the missing causal chain with a plausible narrative.
That behavior is not weakness. It is evidence of a correctly designed trust boundary. It gives operators a reason to escalate, service teams a reason to retrieve deeper logs, and engineering teams a target for improving observability. It also protects the organization from treating generated language as an authoritative incident record.
The Strategic Shift: From Explainable AI to Explainable Physical AI
Classical XAI often asks why a model produced a prediction. Physical AI must ask a larger question: why did the machine produce this physical outcome? That question includes the model, but also the sensor chain, state estimator, planner, safety system, real-time controller, power electronics, actuator, network, software configuration and environment.
The machine that must explain itself is therefore not a robot with a chatbot attached. It is a robot designed for evidence integrity, causal reconstruction and trust calibration from silicon upward.
That architecture creates value far beyond human curiosity. It shortens debugging. It improves commissioning. It supports functional-safety investigations without confusing explanation with safety itself. It strengthens fleet learning because events have context. It improves warranty analysis and predictive maintenance. It makes human oversight more informed. And it creates a disciplined interface between probabilistic AI and deterministic physical control.
As humanoids leave demonstrations and enter factories, warehouses and shared workspaces, capability alone will not define maturity. The next generation of machines will also have to account for their actions. The winning architecture will not be the one that tells the best story. It will be the one that can prove what happened.
References
- Four Principles of Explainable Artificial Intelligence (NISTIR 8312). National Institute of Standards and Technology. https://doi.org/10.6028/NIST.IR.8312
- Artificial Intelligence Risk Management Framework (AI RMF 1.0). National Institute of Standards and Technology. https://doi.org/10.6028/NIST.AI.100-1
- Regulation (EU) 2024/1689, consolidated text 27 July 2026. European Union. https://eur-lex.europa.eu/eli/reg/2024/1689/2026-07-27/eng
- The enforcement framework of the AI Act. European Commission. https://digital-strategy.ec.europa.eu/en/policies/enforcement-ai-act
- Generating Explanations for Autonomous Robots: A Systematic Review. IEEE Access. https://doi.org/10.1109/ACCESS.2025.3535097
- Explainable autonomous robots: a survey and perspective. Advanced Robotics. https://doi.org/10.1080/01691864.2022.2029720
- Personalized causal explanations of a robot’s behavior. Frontiers in Robotics and AI. https://doi.org/10.3389/frobt.2025.1637574
- Trust as a design principle in human–robot collaboration: a review of explainable and adaptive control. Artificial Intelligence Review. https://doi.org/10.1007/s10462-026-11554-1
- ISO 10218-1:2025 Robotics — Safety requirements — Part 1: Industrial robots. International Organization for Standardization. https://www.iso.org/standard/73933.html
- ISO 10218-2:2025 Robotics — Safety requirements — Part 2: Industrial robot applications and robot cells. International Organization for Standardization. https://www.iso.org/standard/73934.html
- ISO 13849-1:2023 Safety of machinery — Safety-related parts of control systems — Part 1: General principles for design. International Organization for Standardization. https://www.iso.org/standard/73481.html
- IEC 62061:2021/AMD2:2026 Safety of machinery — Functional safety of safety-related control systems — Amendment 2. International Electrotechnical Commission. https://webstore.iec.ch/en/publication/92835
- Humanoid robots. Infineon Technologies. https://www.infineon.com/application/humanoid-robots
- AURIX TC3xx Family User’s Manual — Safety Management Unit. Infineon Technologies. https://www.infineon.com/assets/row/public/documents/10/44/infineon-aurix-tc3xx-part1-usermanual-en.pdf
Glossary
- Causal event log
- A time-coherent record of cause–effect relationships among observations, decisions, safety interventions, commands and outcomes.
- Causal provenance
- A traceable record linking an observed event or action to the states, decisions, constraints and commands that produced it.
- Evidence integrity
- Protection that makes recorded evidence attributable, configuration-aware and resistant to undetected alteration.
- Explanation accuracy
- The degree to which an explanation faithfully represents the actual process that generated an output or action, rather than merely sounding plausible.
- Knowledge limits
- Explicit conditions under which a system lacks sufficient confidence, validity or design coverage to provide a reliable answer or action.
- Observability
- The ability to infer or reconstruct relevant internal system state from available measurements, diagnostics and recorded signals.
- Safety arbitration
- The mechanism by which safety constraints can permit, limit, substitute or inhibit an intended robot action before execution.
- Trust calibration
- Aligning human reliance on a robot with its actual competence, confidence, limitations and current operating condition.
Sources
- Artificial Intelligence Risk Management Framework (AI RMF 1.0) · 2023-01-26 · National Institute of Standards and Technology
Frames trustworthy AI across validity, safety, security, transparency, explainability, interpretability and accountability.
https://doi.org/10.6028/NIST.AI.100-1 - AURIX TC3xx Family User’s Manual — Safety Management Unit · 2022 · Infineon Technologies
Documents hardware safety monitoring, alarm handling and diagnosis registers that support root-cause diagnosis and recovery strategies.
https://www.infineon.com/assets/row/public/documents/10/44/infineon-aurix-tc3xx-part1-usermanual-en.pdf - Explainable autonomous robots: a survey and perspective · 2022-02-04 · Advanced Robotics
Frames explanatory capability as a communication requirement for autonomous robots coexisting with humans.
https://doi.org/10.1080/01691864.2022.2029720 - Four Principles of Explainable Artificial Intelligence (NISTIR 8312) · 2021-09-29 · National Institute of Standards and Technology
Defines Explanation, Meaningful, Explanation Accuracy and Knowledge Limits as four principles for explainable AI.
https://doi.org/10.6028/NIST.IR.8312 - Generating Explanations for Autonomous Robots: A Systematic Review · 2025-01-27 · IEEE Access
Finds promising XAR methods but incomplete coverage of complex robot behavior, conceptual inconsistency and a need for robust evaluation.
https://doi.org/10.1109/ACCESS.2025.3535097 - Humanoid robots · 2026 · Infineon Technologies
Maps semiconductor functions across humanoid motor control, sensing, power, connectivity, memory and hardware security.
https://www.infineon.com/application/humanoid-robots - IEC 62061:2021/AMD2:2026 Safety of machinery — Functional safety of safety-related control systems — Amendment 2 · 2026-03-20 · International Electrotechnical Commission
Current amendment to machinery functional-safety requirements for safety-related control systems.
https://webstore.iec.ch/en/publication/92835 - ISO 10218-1:2025 Robotics — Safety requirements — Part 1: Industrial robots · 2025-02 · International Organization for Standardization
Defines safety requirements for industrial robots; useful to the industrial-humanoid discussion while its stated scope exclusions must be respected.
https://www.iso.org/standard/73933.html - ISO 10218-2:2025 Robotics — Safety requirements — Part 2: Industrial robot applications and robot cells · 2025-02 · International Organization for Standardization
Covers integration, commissioning, operation, maintenance and decommissioning of industrial robot applications and cells.
https://www.iso.org/standard/73934.html - ISO 13849-1:2023 Safety of machinery — Safety-related parts of control systems — Part 1: General principles for design · 2023-04 · International Organization for Standardization
Provides design principles for safety-related control-system parts, including software.
https://www.iso.org/standard/73481.html - Personalized causal explanations of a robot’s behavior · 2025-10-08 · Frontiers in Robotics and AI
Stores robot events as cause–effect pairs in a causal log and uses an LLM to refine role-specific language while preserving causal and factual grounding.
https://doi.org/10.3389/frobt.2025.1637574 - Regulation (EU) 2024/1689, consolidated text 27 July 2026 · 2026-07-27 · European Union
Articles 12–14 establish, for applicable high-risk AI systems, requirements around logging, transparency, interpretation and human oversight.
https://eur-lex.europa.eu/eli/reg/2024/1689/2026-07-27/eng - The enforcement framework of the AI Act · 2026-07-31 · European Commission
States current application dates, including 2 December 2027 for Annex III high-risk systems and 2 August 2028 for high-risk AI embedded in regulated products.
https://digital-strategy.ec.europa.eu/en/policies/enforcement-ai-act - Trust as a design principle in human–robot collaboration: a review of explainable and adaptive control · 2026-04-20 · Artificial Intelligence Review
Treats trust calibration as a technical design objective and identifies gaps in metrics, long-term validation and integration of explainability with control.
https://doi.org/10.1007/s10462-026-11554-1

